Key Takeaways
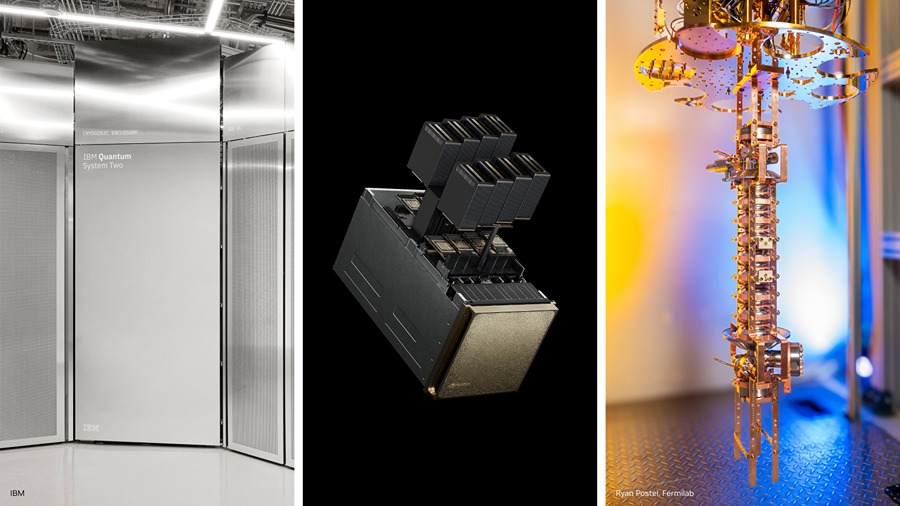
- Tri‑party partnership – NVIDIA, IBM, and DOE’s Fermilab are co‑designing a modular quantum‑computing platform that blends NVIDIA accelerated hardware with IBM’s latest quantum processors.
- Hardware integration – NVIDIA DGX B200 systems will be colocated with IBM’s Quantum Nighthawk chip, the fastest quantum processor in IBM’s roadmap to date.
- Algorithmic breakthrough – A new NVIDIA‑derived quantum decoding algorithm is up to 13,000 × faster than the best publicly reported alternatives, shrinking design‑cycle time from 12 weeks to 45 minutes.
- Workflow unification – Slurm scheduler extensions will let supercomputing centers treat quantum nodes as first‑class resources, simplifying job submission and resource management.
- Target applications – The platform focuses on error‑correction code development, high‑energy‑physics simulations, and scaling strategies for linked quantum modules.
Introduction
NVIDIA has formalized a three‑way collaboration with IBM and the U.S. Department of Energy’s Fermi National Accelerator Laboratory (Fermilab). The joint effort aims to accelerate the transition from laboratory‑scale quantum devices to modular, networked quantum computers that can be harnessed alongside conventional HPC clusters for scientific discovery.
Modular Quantum Co‑Design Platform
Integrated Hardware Stack
- NVIDIA DGX B200 – Each system delivers 8 × NVIDIA H100 Tensor Core GPUs, 640 GB of high‑bandwidth memory (HBM3), and a 400 Gb/s NVLink mesh.
- IBM Quantum Nighthawk – IBM’s latest superconducting processor, featuring 127 qubits with a reported two‑qubit gate fidelity of 99.9 % and a quantum volume of 2^127.
Both systems will be physically colocated in dedicated labs at Fermilab, creating a “quantum‑classical” node that can execute hybrid workloads with sub‑microsecond latency between GPU and qubit control electronics.
Research Capabilities
The platform enables scientists to:
| Capability | Traditional Approach | Co‑Design Platform Advantage |
|---|---|---|
| Error‑correction code testing | Run on simulated qubits; cycle times > hours | Real‑time execution on Nighthawk; cycle times < seconds |
| Decoding algorithm speed | Up to 12 weeks for full parameter sweep | 45 minutes with new NVIDIA algorithm |
| Scalability studies | Limited to single‑chip models | Multi‑chip modular linking with deterministic latency measurement |
These capabilities are especially relevant for high‑energy and nuclear physics (HENP) experiments that demand massive data throughput and ultra‑low error rates.
Quantum Decoding Algorithm: Speed Records
NVIDIA unveiled a custom decoding routine that leverages H100 Tensor Cores and CUDA‑optimized kernels. Benchmarks show:
- 13,000 × speedup over the previous state‑of‑the‑art decoder (e.g., the PyQEC library).
- Latency reduction: from ≈ 12 weeks of batch processing on a conventional CPU cluster to ≈ 45 minutes on a single DGX B200.
- Throughput: > 10⁹ bits/s of syndrome data processed, enabling real‑time error‑correction loops for > 100‑qubit systems.
The algorithm’s performance stems from parallel syndrome extraction, tensor‑core‑accelerated belief‑propagation, and on‑GPU memory residency that eliminates host‑device transfers.
Slurm Integration for Quantum Workflows
To bridge the gap between classical supercomputers and quantum processors, NVIDIA and IBM are extending the Slurm workload manager:
| Feature | Description |
|---|---|
| Quantum node flag | #SBATCH --qnode marks a job as requiring quantum resources. |
| Dynamic resource allocation | Scheduler automatically provisions GPU, CPU, and quantum control hardware in a single allocation. |
| Unified accounting | Usage metrics for quantum cycles are logged alongside CPU/GPU hours, simplifying cost tracking. |
This integration allows existing HPC users to submit hybrid jobs without learning a new orchestration layer, fostering broader adoption of quantum acceleration.
Anticipated Scientific Impact
The joint platform is positioned to accelerate several research fronts:
- Particle physics: Simulating lattice QCD on quantum‑enhanced circuits could reduce simulation time from months to weeks.
- Materials science: Hybrid quantum‑classical variational algorithms will explore strongly correlated electron systems with higher fidelity.
- Algorithmic research: Rapid prototyping of fault‑tolerant schemes will inform the design of future modular quantum processors.
Bottom Line
NVIDIA, IBM, and Fermilab are converging cutting‑edge GPU acceleration, the fastest IBM quantum chip, and DOE expertise into a single modular platform. By delivering a 13,000‑fold decoding speedup, integrating quantum nodes into Slurm, and colocating DGX B200 systems with IBM’s Nighthawk, the collaboration dramatically shortens the research cycle for quantum error‑correction and high‑energy‑physics applications. This co‑design effort not only bridges the classical‑quantum divide but also sets a concrete roadmap for scalable, modular quantum computers that can be deployed within existing supercomputing ecosystems.