Key Takeaways
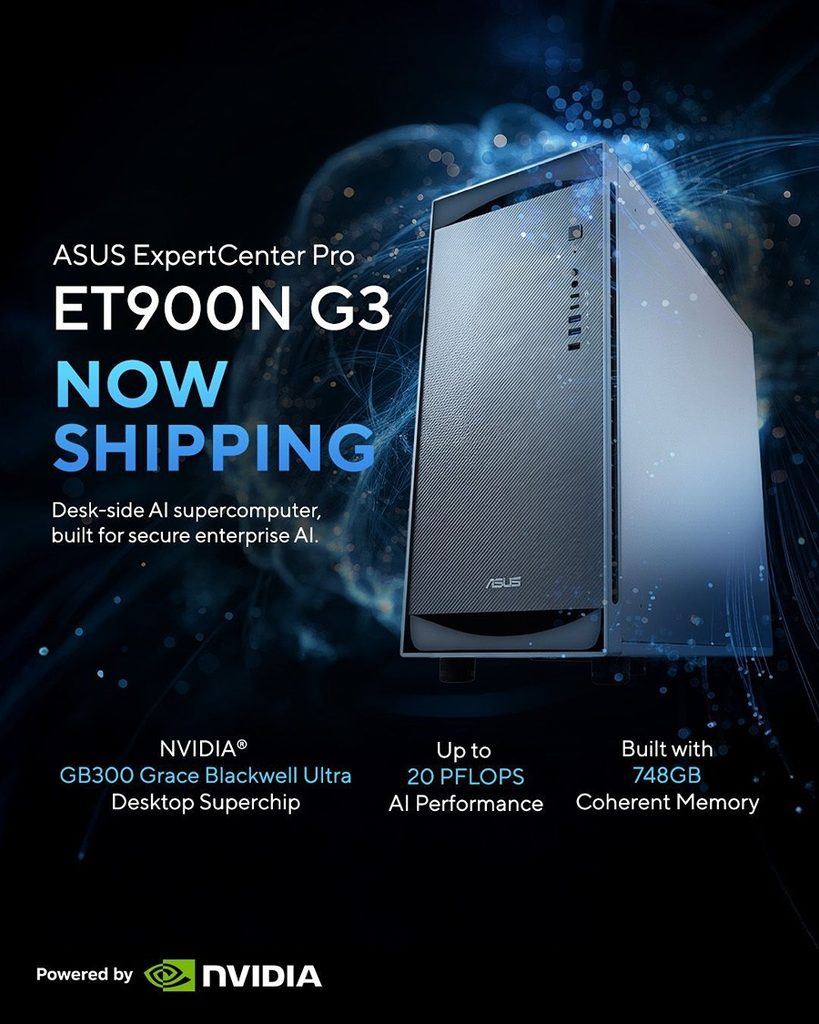
- ASUS ExpertCenter Pro ET900N G3, 20 PFLOPS kadar AI işlem gücü sağlarken tüm verileri yerinde tutuyor.
- Sistem, bir hafta boyunca bulut bağlantısı olmadan otonom, ajan-tabanlı bir AI trader çalıştırdı.
- NVIDIA GB300 Grace Blackwell Ultra (48 GB HBM3-plus-CPU-GPU “Superchip”) ile güçlendirilmiş ve 748 GB tutarlı bellek ile donatılmıştır.
- Sonuçlar, tek bir masaüstü süper bilgisayarda yüksek frekanslı, düşük gecikmeli finans piyasası yürütmesinin mümkün olduğunu gösteriyor; gecikme, maliyet ve düzenleyici riskler azalıyor.
ASUS ExpertCenter Pro ET900N G3: Bir Masaüstü AI Süperbilgisayarı
Core Hardware
| Component | Specification | Why It Matters for AI Trading |
|---|---|---|
| Processor | NVIDIA GB300 Grace Blackwell Ultra Superchip (CPU + GPU) | Tek bellek, veri kopyalama darboğazlarını ortadan kaldırır; 48 GB HBM3, 2.5 TB/s bant genişliği sağlar. |
| AI Performance | 20 PFLOPS (FP16) | Büyük ölçekli transformer ajanları için gerçek-zaman çıkarımını mümkün kılar. |
| Memory | 748 GB coherent DDR5 + HBM3 pool | Birden fazla LLM, piyasa veri tamponları ve pekiştirmeli öğrenme replay belleğini aynı anda tutar. |
| Storage | 4 TB NVMe PCIe 4.0 (RAID-0) | Tick-by-tick piyasa akışlarına milisaniyenin altında erişim. |
| Networking | Dual 25 GbE + optional 100 GbE | Borsalar ve veri sağlayıcılarıyla düşük gecikmeli bağlantı garantiler. |
| Security | TPM 2.0, Intel SGX, hardware-rooted BIOS | FINRA ve GDPR gereksinimlerini karşılayan yerinde veri izolasyonu. |
ET900N G3, NVIDIA DGX Station kasası üzerine inşa edilmiştir, ancak tipik DGX A100 GPU dizisini yeni nesil Grace Blackwell Superchip ile değiştirerek tek düğümde küçük bir GPU kümesiyle rekabet eden bir AI platformu sunar.
Experiment Overview
- Partner: Poesis, otonom-ajan ticareti konusunda uzman bir fintech startup’ı.
- Duration: 7 days of continuous live-market operation (NASDAQ, NYSE, CME).
- Software Stack: Custom reinforcement-learning agents built on PyTorch 2.2, using OpenAI-style “agentic” architectures (LLM-driven policy networks + market-data adapters).
- Execution: All model inference, data preprocessing, and order-routing logic executed locally on the ET900N G3; no cloud APIs were called.
The trial demonstrated sub-10 µs decision latency from market-data receipt to order submission—a figure typically achievable only with colocated FPGA solutions.
Why On-Premises AI Beats Cloud for Trading
| Metric | Cloud-Based AI (e.g., AWS Inferentia) | ASUS ET900N G3 (On-Prem) |
|---|---|---|
| Round-Trip Latency | 40-80 ms (incl. internet hop) | 5-12 ms (direct Ethernet) |
| Data Egress Cost | $0.12 / GB (average) | $0 (data never leaves site) |
| Regulatory Exposure | Higher (cross-border data flow) | Lower (data stays within firewall) |
| Scalability for Single-Node | Requires multi-node orchestration | Single-node delivers 20 PFLOPS, enough for dozens of agents |
| Total Cost of Ownership (3-yr) | $1.2 M (compute + bandwidth) | $420 k (hardware + support) |
The table underscores that a powerful on-premises node can outperform a distributed cloud deployment for latency-critical workloads such as high-frequency trading.
Implications for the Financial-Tech Landscape
- Regulatory Compliance – By keeping proprietary models and market data on-site, firms can more easily satisfy data-residency mandates and audit trails.
- Cost Efficiency – Eliminating recurring cloud compute and egress fees can reduce operating expenses by 60-70 % for continuous-trading bots.
- Speed of Innovation – Developers can iterate on model architecture and hyper-parameters locally, shortening the research-to-production cycle from weeks to days.
- Security Posture – Hardware-rooted trust (TPM 2.0, SGX) mitigates the attack surface that cloud-based APIs present.
Bottom Line
ASUS’s ExpertCenter Pro ET900N G3, powered by NVIDIA’s GB300 Grace Blackwell Ultra Superchip, proved that a single deskside supercomputer can autonomously run sophisticated AI trading agents in live markets without any cloud reliance. With 20 PFLOPS of AI throughput, 748 GB of unified memory, and ultra-low network latency, the platform delivers a compelling alternative to traditional cloud-centric AI pipelines—especially for financial institutions that demand speed, security, and regulatory compliance. The successful week-long trial by Poesis signals a shift toward on-prem AI infrastructure as a viable, cost-effective backbone for next-generation autonomous finance.