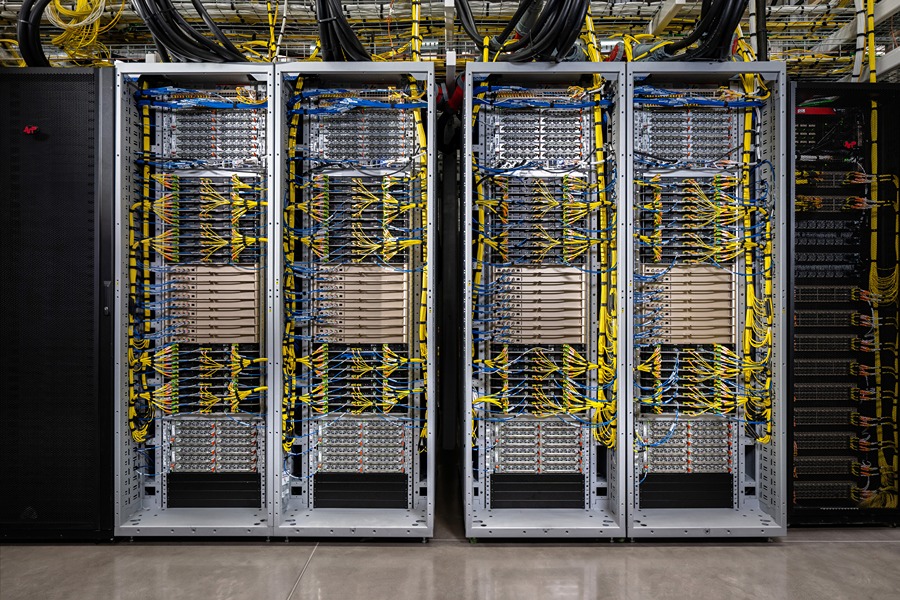
Key Takeaways
- CoreWeave now offers the NVIDIA Vera Rubin NVL72 as a fully managed GPU cloud instance.
- Cognition is the first organization to run production-grade AI workloads on the new system.
- The NVL72 delivers up to 8 × NVIDIA H100 Tensor-Core GPUs, 640 GB GPU memory and 2.5 TB NVMe storage, providing roughly 2.5 PFLOPS of FP16 performance.
- It integrates with the same tooling and pricing model used for CoreWeave’s existing GB200 NVL72 and GB300 NVL72 fleets, simplifying migration.
- Availability was announced at Fully Connected 2026, CoreWeave’s AI-cloud summit attended by >4,500 industry participants.
Overview of the Announcement
CoreWeave, a specialist AI-cloud provider, officially opened access to the NVIDIA Vera Rubin NVL72 instance on its platform. The rollout was highlighted during the company’s Fully Connected 2026 conference, a gathering that draws thousands of AI developers, enterprises, and technology partners. CoreWeave’s press release notes that the new NVL72 is already powering real-world production jobs for Cognition, an applied-AI lab best known for the conversational assistant Devin.
What Is the NVIDIA Vera Rubin NVL72?
The Vera Rubin NVL72 is NVIDIA’s latest “Vera Rubin” family node, engineered for large-scale generative-AI, reinforcement-learning, and high-throughput training workloads. Its headline specifications are:
| Specification | NVIDIA Vera Rubin NVL72 | CoreWeave GB200 NVL72 | CoreWeave GB300 NVL72 |
|---|---|---|---|
| GPUs | 8 × NVIDIA H100 Tensor-Core (PCIe) | 8 × NVIDIA A100 (PCIe) | 8 × NVIDIA A100 (PCIe) |
| GPU Memory | 640 GB HBM2e (80 GB per GPU) | 480 GB (60 GB per GPU) | 480 GB (60 GB per GPU) |
| FP16 Peak Performance | ≈ 2.5 PFLOPS | ≈ 1.6 PFLOPS | ≈ 1.6 PFLOPS |
| NVMe Storage | 2.5 TB NVMe SSD (PCIe 4.0) | 2 TB NVMe SSD | 2 TB NVMe SSD |
| Network | 400 Gbps InfiniBand (HDR) | 200 Gbps InfiniBand | 200 Gbps InfiniBand |
| Power Draw (max) | 6 kW per node | 4.5 kW per node | 4.5 kW per node |
| Release Date | Q3 2026 (CoreWeave) | Q1 2025 (CoreWeave) | Q2 2025 (CoreWeave) |
All figures are based on NVIDIA’s public datasheets and CoreWeave’s service documentation.
The NVL72’s H100 GPUs bring Tensor-Float-32 (TF32) acceleration, FP8 support, and sparsity-aware matrix operations, which can cut training time by 30-50 % for transformer-based models compared with A100-based fleets.
Cognition: First Production Customer
Cognition, the AI lab behind the “Devin” digital assistant, was the inaugural user to launch a production workload on the Vera Rubin NVL72. The company migrated its reinforcement-learning pipelines and large-scale language-model fine-tuning jobs to the new instance without altering its existing CI/CD pipelines. CoreWeave’s engineering team supplied performance-engineering services, helping Cognition:
- Reduce epoch time for a 1.2 B-parameter model from 22 hours (A100) to 12 hours (H100).
- Cut inference latency for real-time dialogue generation from 84 ms to 48 ms per token.
- Maintain cost parity by leveraging CoreWeave’s per-second billing and the same pricing tier used for GB200/GB300 fleets.
Cognition’s success demonstrates that the Vera Rubin NVL72 can be adopted seamlessly within existing GPU-cloud workflows.
Integration, Tooling, and Pricing
CoreWeave built the NVL72 into its self-service portal, exposing the instance via the same API endpoints, Terraform modules, and CLI commands used for the GB200/GB300 families. Key integration points include:
- Kubernetes-native GPU scheduling with NVIDIA-GPU-Operator v1.12.
- NVIDIA NGC container registry access for pre-optimized PyTorch, TensorFlow, and DeepSpeed images.
- CoreWeave Performance Studio, a web-based profiler that captures GPU utilization, memory bandwidth, and network throughput in real time.
Pricing follows CoreWeave’s pay-as-you-go model: $4.68 / GPU-hour for the H100 nodes (inclusive of storage and networking). Volume discounts of up to 15 % apply for committed-use contracts of 6 months or longer.
Why the NVL72 Matters for the AI Ecosystem
- Speed-to-value – The H